Layered vs. Adjacency
kpnn2 has two parsers, and the one you
call fixes the shape of everything you build afterwards.
parse_layered() ranks nodes by depth and
returns a LayeredSpec; parse_adjacency() puts
every node in one state vector, a
single vector over all nodes, and returns an
AdjacencySpec.
The same source / target edgelist goes through either one,
and a directed acyclic graph (DAG) is valid
for both, so the layout is your choice. Only
parse_adjacency() allows cycles and self-loops.
This page is the difference between the two
specs, the frozen structures the parsers
return.
Feedforward example is a feedforward
parse_layered() workflow.
Cyclic graph example is a
parse_adjacency() workflow on a graph with a feedback loop.
Transformer example and
Time-series example use that same
packed layout: they need named nodes and
packed pairs, not
hop rectangles — a hop being everything
entering one layer.
How edges are stored
The toy is A -> H -> C plus the skip
A -> C, an edge whose endpoints are more than one layer apart:
| source | target |
|---|---|
| A | H |
| H | C |
| A | C |
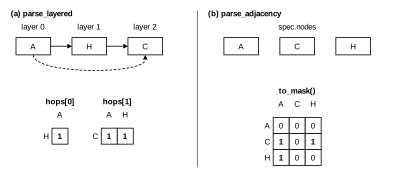
Figure 1. The same DAG parsed two ways. Layered ranks nodes
and puts every incoming edge in one packed hop (the skip is a
pair of hops[1]). Adjacency puts every node in one
alphabetical state vector and every edge in packed indices.
parse_layered() gives every node a depth,
its longest path from the inputs: A is layer 0, H is layer 1,
C is layer 2.
Each layer after the first owns one hop, holding all of that
layer's incoming edges. hops[0] is the packed hop into H;
hops[1] is the hop into C, which reads both earlier layers
because the skip makes A a parent of C alongside H.
Skip edges is the algorithm for that extra
source layer.
parse_adjacency() ranks nothing. spec.nodes gives the
state-vector order, A, C, H, alphabetically. Edges become
packed source_index / target_index pairs over that order,
and spec.to_mask() renders them as a 3×3 square where
mask[target, source] is 1 for an original edge. Row A is
all zeros because A is an input. The skip is one more pair:
mask[C, A] = 1. There are no hops and no skips; depth does
not exist in this layout.
input_nodes, hidden_nodes, and output_nodes are the same
on both specs (A, H, and C).
How you compute
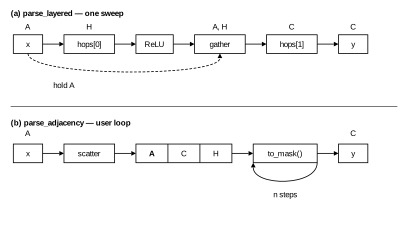
Figure 2. How you compute on that toy. Layered is one
sweep: hold A, gather it with H, then hops[1]. Adjacency
scatters A into the state and applies
MaskedLinear(spec.to_mask()) in a loop you own.
On a LayeredSpec you apply one PackedLinear per hop. Keep
every layer you produce in saved, because a later hop may read
it. gather_hop_inputs() concatenates the source layers a hop
reads; hops[0] always reads layer 0 alone, so the gather that
matters here is the one into hops[1].
saved = {0: x}
last = len(spec.hops) - 1
for index, hop in enumerate(spec.hops):
    sources = kpnn2.gather_hop_inputs(
        saved,
        hop,
    )
    hidden = self.hops[index](sources)
    if index < last:
        hidden = self.acts[index](hidden)
    saved[hop.target_layer] = hidden
self.acts is nn.ModuleList([nn.ReLU() for _ in spec.hops]).
The output hop stays linear.
self.hops[index] is PackedLinear on that hop's packed
indices. MaskedLinear(hop.to_mask()) is the dense hatch.
Feedforward example writes that module.
Skip edges shows why gather raises if a
source layer was never stored.
On an AdjacencySpec there is one square multiply. Aligned
inputs do not fit the state vector: align_inputs() returns
len(spec.input_index) positions, not spec.state_dim, so
you gather those columns and scatter them in at
spec.input_index. Input rows of
to_mask() are structurally zero (fan_in == 0), so the
multiply drives those units to zero: the scatter is required,
and so is repeating it on every pass if you loop.
core = kpnn2.MaskedLinear(spec.to_mask())
state = torch.zeros(
    x.shape[0],
    spec.state_dim,
)
for tap in self.taps:
    state = state.index_copy(
        -1,
        self.input_index,
        x,
    )
    state = tap(self.act(core(state)))
y = state[:, spec.output_index]
self.input_index is a buffer,
torch.as_tensor(spec.input_index). self.taps is an
nn.ModuleList of nn.Identity, one per step, and that is
what Captum hooks. self.act is an nn.ReLU. The shared
map stays a normal child of the module. index_copy returns
a new tensor, so the activation saved for backward is left
alone.
n_steps is yours; kpnn2 does not unroll time. With x held
fixed, that loop is the shared-state one
Cyclic graph example trains on a
graph with a feedback edge. When x changes at each step, it is
a time-series knowledge-primed neural network
(KPNN); see
Time-series example.
This toy is small, so MaskedLinear is appropriate; for large
node counts and RAM see PackedLinear. The
same packed indices can feed PackedMultiheadAttention
(chunk_size when live-pair gathers strain RAM); that
walkthrough is the
Transformer example.
How to choose a parser
- A feedforward DAG goes through
parse_layered(). That is the usual KPNN. - Use
parse_adjacency()for cycles and self-loops (parse_layered()raises on those), a shared-state or time-series loop, or packed attention. It is the packed layout: one state vector and packed edge indices. - A DAG may go through
parse_adjacency()if you want that layout. The package never inspects the graph to pick a parser. - Both still need at least one in-degree-0 node and one out-degree-0 node. A pure ring, or a lone self-loop, is rejected on both sides.
Changing the prior
Specs are frozen after parse, on both layouts.
- To drop edges while training continues, keep the spec and
put a keep-mask in
constraint=. See Pruning during training. - To grow the prior, or to remove edges and retrain a smaller model, edit the edgelist, parse it again, and copy the surviving weights by name. See Changing the prior (reparse).
Do not copy_ a whole weight or call load_state_dict
across two priors: both copy by position, so a value can
land on a different named edge.