Skip edges
parse_layered() ranks a DAG into layers. An original edge whose
endpoints are more than one layer apart is a skip. This page
is the algorithm for that edge, how kpnn2 writes it as a hop
mask, and one worked example.
Algorithm
Adjacent edges are the easy case: compute each layer from the one below it. A skip still has to reach its target after the layers in between have been computed.
That skip is an extra parent of the target, not a second
kind of node. The source is not copied through dummy units, and
kpnn2 never inserts identity neurons or generated names.
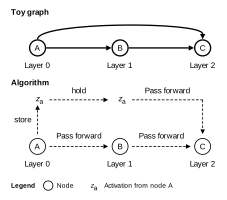
Figure 1. Store the source activation, hold it across the next hop, and pass it into the target together with the adjacent parent. Solid arrows are graph edges; dashed arrows are the forward pass. A, B, and C are a three-node toy. Figure 2 uses a larger graph.
The computational steps are store, hold, and pass forward. In symbols, for the toy:
C = f( w_{B→C} z_B + w_{A→C} z_A + b_C )
The skip weight is an ordinary incoming weight on C.
Hop masks
kpnn2 writes that algorithm as one hop mask per layer after
the inputs. Every edge entering a layer is a column of that
mask, skips included. Adjacent and skip edges then share one
MaskedLinear. spec.skips is metadata for inspection; the
forward pass never reads it.
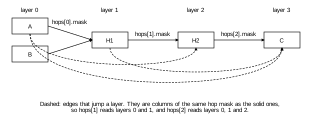
Figure 2. Figure 1 written as hop masks on the graph used in
the example below. hops[1] reads layers 0 and 1, and hops[2]
reads layers 0, 1 and 2. Solid and dashed edges are the same
matrix multiply; the dashes only mark which edges jump a layer.
gather_hop_inputs(saved, hop) concatenates the source layers
in mask-column order. The mask zeros columns that are not
edges. You do not pick skip nodes by name.
Three properties follow, and they are the reason the design looks like this:
- No edge can be dropped silently. Applying a hop applies
every parent of its target at once. There is no second call to
remember, and
gather_hop_inputs()raisesKpnn2Errorif a layer that a hop reads was never stored. - The fan-in is right.
MaskedLinearinitializes each output row from that row's mask degree. Because skip parents sit in the same row, a unit with two adjacent and three skip parents is initialized with fan-in five, not two. - A skip weight is an ordinary weight. One weight per incoming
edge, all in one matrix, all drawn from the same degree-aware
initialization. There is no skip bias: one bias per unit stays
on
MaskedLinear.
In a larger graph the same three steps loop:
saved = {0: x}
for hop in spec.hops:
    sources = kpnn2.gather_hop_inputs(saved, hop)
    hidden = layer(sources)
    saved[hop.target_layer] = hidden
layer is MaskedLinear(hop.mask).
Getting started shows that loop on a graph without skips. The loop does not change here, because skips already sit inside those masks.
Example
The rest of this page unrolls Figure 2 so each hop is a named line.
Inputs A and B, hidden units H1 and H2, output C.
Adjacent edges are A -> H1, B -> H1, H1 -> H2, and
H2 -> C. Skips are A -> H2, H1 -> C, and A -> C.
import pandas as pd

import kpnn2

edgelist = pd.DataFrame(
    {
        "source": ["A", "B", "H1", "H2", "A", "H1", "A"],
        "target": ["H1", "H1", "H2", "C", "H2", "C", "C"],
    }
)
spec = kpnn2.parse_layered(edgelist)
print(spec.layer_nodes)
print([f"{s.source} -> {s.target}" for s in spec.skips])
(('A', 'B'), ('H1',), ('H2',), ('C',))
['A -> H2', 'H1 -> C', 'A -> C']
The masks
spec.hops has one mask per layer after the inputs. Each row is
the target unit; each column is a parent, including skips. A 0
is an absent edge (B never feeds H2 or C).
hop0, hop1, hop2 = spec.hops
print(
    pd.DataFrame(
        hop0.mask.numpy(), columns=list(hop0.source_nodes), index=["H1"]
    )
)
print()
print(
    pd.DataFrame(
        hop1.mask.numpy(), columns=list(hop1.source_nodes), index=["H2"]
    )
)
print()
print(
    pd.DataFrame(
        hop2.mask.numpy(), columns=list(hop2.source_nodes), index=["C"]
    )
)
ones = int(hop0.mask.sum() + hop1.mask.sum() + hop2.mask.sum())
print(ones, "ones in the masks,", len(edgelist), "edges")
      A    B
H1  1.0  1.0

      A    B   H1
H2  1.0  0.0  1.0

     A    B   H1   H2
C  1.0  0.0  1.0  1.0
7 ones in the masks, 7 edges
hops[0] reads only (A, B), because H1 can only have
layer-0 parents. hops[1] also reads A, since A -> H2 jumps
a layer. hops[2] reads A, H1, and H2.
The ones across all three masks add up to the number of rows in the edgelist. That equality is the guarantee: every prior-knowledge edge is in exactly one mask.
The module
A normal nn.Module: __init__ builds one MaskedLinear per
hop, forward applies them in order. The hop into H1 reads
only the input, so it takes x directly. The hops into H2 and
C also need earlier activations, so gather_hop_inputs()
concatenates those layers into one tensor whose columns match the
mask.
No skip object is applied anywhere. Bias is off so the numbers below stay readable.
import torch
import torch.nn.functional as F
from torch import nn


class Net(nn.Module):
    def __init__(self, spec: kpnn2.LayeredSpec):
        super().__init__()
        self.spec = spec
        self.to_h1 = kpnn2.MaskedLinear(spec.hops[0].mask, bias=False)
        self.to_h2 = kpnn2.MaskedLinear(spec.hops[1].mask, bias=False)
        self.to_c = kpnn2.MaskedLinear(spec.hops[2].mask, bias=False)

    def forward(self, x):
        h1 = F.relu(self.to_h1(x))
        h2_in = kpnn2.gather_hop_inputs({0: x, 1: h1}, self.spec.hops[1])
        h2 = F.relu(self.to_h2(h2_in))
        c_in = kpnn2.gather_hop_inputs({0: x, 1: h1, 2: h2}, self.spec.hops[2])
        self.h1, self.h2 = h1, h2
        return self.to_c(c_in)


model = Net(spec)
Numerical check
forward returns C. self.h1 and self.h2 are stored only so
this check can print the hidden units.
Pin every adjacent weight to 1, and the skip weights to
w_{A→H2} = 0.3, w_{H1→C} = 0.2, w_{A→C} = 0.1. Columns
follow source_nodes above, so absent parents stay 0.
For input A = 2, B = 0:
H1 = relu(A + B) = 2
H2 = relu(0.3 A + H1) = relu(2.6) = 2.6
C  = 0.1 A + 0.2 H1 + H2 = 3.2
For A = -1, B = 0, ReLU zeros the path through H1 and H2,
but the skip A -> C still contributes:
H1 = relu(-1) = 0
H2 = relu(0.3 (-1) + 0) = 0
C  = 0.1 (-1) + 0.2 * 0 + 0 = -0.1
Assigning layer.weight = pinned writes through the mask
parametrization into the trainable tensor; the mask then hides
whatever the pinned matrix says about absent edges.
model.to_h1.weight = torch.tensor([[1.0, 1.0]])
model.to_h2.weight = torch.tensor([[0.3, 0.0, 1.0]])
model.to_c.weight = torch.tensor([[0.1, 0.0, 0.2, 1.0]])

c = model(torch.tensor([[2.0, 0.0]]))
print(
    f"A=2  H1, H2, C: {model.h1.item():.1f},"
    f" {model.h2.item():.1f}, {c.item():.1f}"
)
c = model(torch.tensor([[-1.0, 0.0]]))
print(
    f"A=-1 H1, H2, C: {model.h1.item():.1f},"
    f" {model.h2.item():.1f}, {c.item():.1f}"
)
A=2  H1, H2, C: 2.0, 2.6, 3.2
A=-1 H1, H2, C: 0.0, 0.0, -0.1
Checks
The fan-in that MaskedLinear initializes from is the row degree
of the hop mask, so it counts skip parents. A hop that reads a
layer you never stored is an error, not a silent omission.
print("H1 fan-in", int(spec.hops[0].mask.sum()))
print("H2 fan-in", int(spec.hops[1].mask.sum()))
print("C fan-in", int(spec.hops[2].mask.sum()))

x = torch.tensor([[2.0, 0.0]])
try:
    kpnn2.gather_hop_inputs({0: x}, spec.hops[2])
except kpnn2.Kpnn2Error as error:
    print(error)
H1 fan-in 2
H2 fan-in 2
C fan-in 3
saved is missing layer 1. The hop into layer 3 reads layers [0, 1, 2].